Retrieval Engineering with Python
Your agent is only as good as what it can retrieve. That layer is where it breaks.
Cohort 1 taught you to build an agent. This one teaches you to build the retrieval system an agent can actually trust: one that indexes a real codebase, answers with provenance, and proposes patches that pass the target repo's own test suite before you ever see them.
Most courses bolt retrieval on at the end, as the thing you add so the model stops making things up. We run the opposite way. Retrieval is the whole subject, and nothing merges without a number behind it.
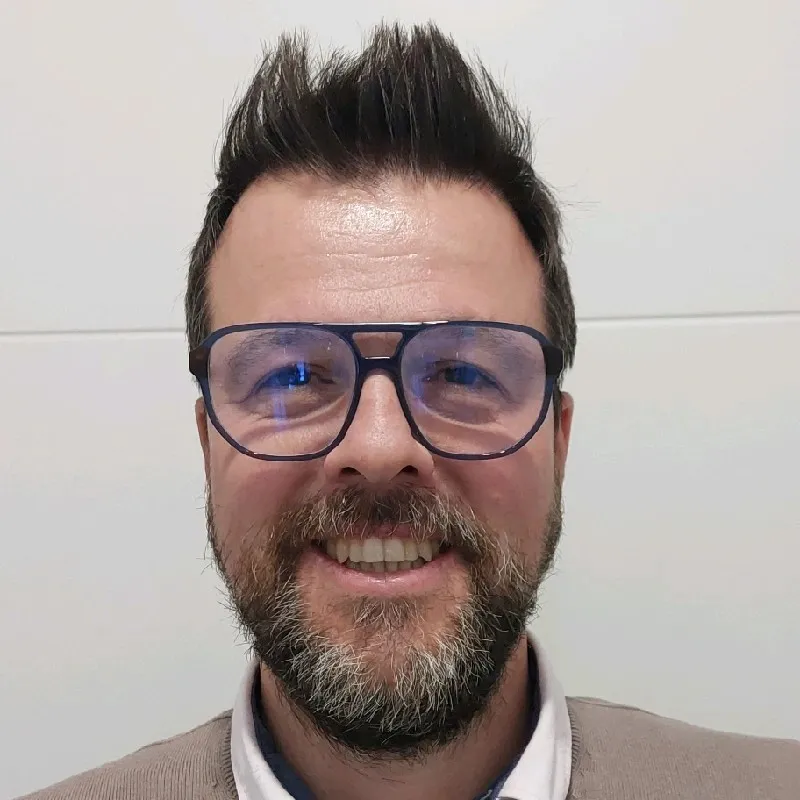
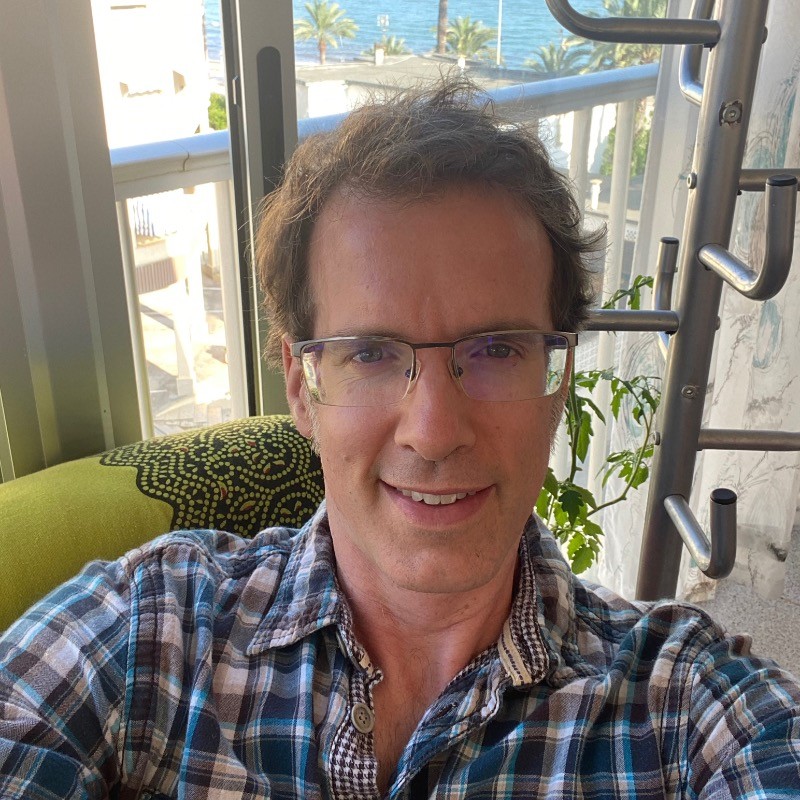 Coached by Juanjo & Bob · meet your coaches ↓
Over 8 to 10 weeks you build askrepo, a command-line coding assistant that indexes a software repository and handles three kinds of request: how does this error propagate, where is this contract defined and who implements it, and add this validation and return a patch that already passes the tests. Every answer cites the chunks that back it. An answer without provenance is a failure, and there is a test that checks for it.
Join the waitlist for the founding cohort
This one is being built now, and the first cohort is small. Add your email to get first word when seats open, founding pricing, and the reference golden set the day it ships. No commitment; leave anytime.
No spam. Unsubscribe anytime.
Why this is the hard, valuable layer
An agent that calls an API is a weekend project now. An agent you can trust on a 500k-token codebase is not. The gap is retrieval: chunking that survives edits, hybrid search that knows when a question is lexical and when it is semantic, an index that stays fresh as the code changes, and an evaluation harness that tells you the truth instead of a demo that happened to work once.
This is the layer a generalist AI course covers in two sessions. It is also the layer that decides whether your agent is a toy or a tool. We spend the whole cohort here.
The thesis is one line: a retrieval system is designed by measuring it. You will not take our word for what works. You build a golden set in week one, CI breaks against it from week one, and every design decision after that is settled by your own curves.
How it works: Test-Driven Coaching
Same method as Cohort 1, turned up. Most courses give you videos to watch. This one gives you tests to pass, and two senior engineers to review the code you wrote to pass them.
- Step 1: RED. Each week you receive complete, runnable pytest files, all failing. No stubs, no TODOs. The tests are the spec.
- Step 2: Write. You write the production code against frozen contracts (Protocols and Pydantic models we provide), so you build the retrieval engine, not the plumbing.
- Step 3: GREEN. Tests pass, CI goes green, and the week's metric clears its threshold. "Done" is objective.
- Step 4: The measurement. Green tests are the baseline. Every week also produces a table or a curve from your own data: recall versus latency, chunk stability under edits, cost per query, mean age of served content. You justify your operating point in writing.
- Step 5: The senior review. Every PR gets a line-by-line review: contracts respected, layers clean, error handling honest, and why you chose this approach over another.
Around 230 tests across the full track. Every capability has a test that proves it, and a benchmark that measures it. That measurement block is the difference between this and a long tutorial, and it is non-negotiable.
What you'll be able to do, week by week
The recommended 10-week track. An 8-week variant compresses the same arc.
Baselines & measurement
- Write a 20-question golden set first
- Measure three baselines against it
- Prompt, response & tool-result caching
- Cost, time-to-first-token, accuracy
- A table that says which weeks to build
Idempotent ingestion
- Filesystem & Git source adapters
- Canonical docs, stable identifiers
- Content-addressable hashing
- Change & deletion detection
- Re-ingest without duplicating
Stable chunking
- Fixed, recursive, structural, AST
- Overlap and parent-context enrichment
- Chunk stability under edits (own metric)
- Boundaries that survive a 3-line change
- The dependency that week 9 rests on
Vector index & the curve
- Embeddings, dimensionality, batching
- pgvector on Docker
- Exact vs approximate, index params
- Filters pushed into the index
- Your own recall-vs-latency curve
Hybrid retrieval & reranking
- BM25 with FTS5, reciprocal rank fusion
- Cross-encoder reranking
- Query expansion and routing by type
- Lexical for location, dense for meaning
- Latency traded per point of nDCG
Evaluation & failure analysis
- Golden set grows to 100 pairs
- recall@k, MRR, nDCG, faithfulness
- RAGAS plus your own metrics
- Classify 20 real failures by cause
- Decide where to invest next
Agent with tools
- search, read_file, list_symbols, run_tests
- Reason-and-act loop, token budget
- Context pruning, stopping criteria
- The query becomes a decision the model makes
- Measured against your golden set
Propose & verify
- LLM proposes a patch
- Apply in isolation, run the target suite
- Static analysis, revert on failure
- Retry with the failure output as context
- An oracle, not a council of agents
Freshness & reindexing
- Revisit policy, change-rate modeling
- Incremental reindexing, not full rebuilds
- Hash-tree divergence detection
- Cost of reindexing vs stale answers
- Metric: mean age of served content
Security, observability, capstone
- Instruction injection via retrieved content
- Tool-output isolation, least privilege
- A poisoned corpus you have to survive
- OpenTelemetry, per-request cost
- Final defense: your system, your curves
Tech stack: Python 3.13, uv, Typer, Postgres + pgvector, SQLite FTS5, RAGAS, OpenTelemetry, pytest, ruff, mypy. By hand for everything that is the learning, a library for everything else.
Join the waitlist for the founding cohort
This one is being built now, and the first cohort is small. Add your email to get first word when seats open, founding pricing, and the reference golden set the day it ships. No commitment; leave anytime.
No spam. Unsubscribe anytime.
What you walk away with
A measured system, not an app
Your own askrepo repository on GitHub: CI green and above metric thresholds, indexing a real codebase, answering with provenance, and proposing patches verified by test execution. Plus the curves that prove each choice.
The instinct nobody teaches
You leave able to look at a retrieval pipeline and know where it leaks: recall, precision, or freshness. You debug with numbers, not vibes. That transfers to every RAG and agent system you touch afterward.
A code-review history
Every week, a line-by-line PR review from two senior engineers. You finish with a GitHub trail that shows engineering judgment on a genuinely hard problem, not tutorial copy-paste.
Everything included
- ~230 tests, pre-written and all red. Complete, runnable pytest files each week. Tests are the assignment; your code is the answer.
- Frozen contracts, handed to you. Protocols and Pydantic models provided and locked, so you build the retrieval engine and skip the plumbing.
- A reproducible benchmark harness every week. A table or a curve from your own data. This is what makes it engineering.
- Line-by-line PR review on every push. Two senior coaches on architecture, naming, and design tradeoffs. This is the product.
- Weekly live call with both coaches, recorded. Bob on architecture, Juanjo on AI & infra, plus async support all week.
- A solution branch each week. Fall behind and you still have a green reference to catch up against.
- Devcontainer and docker compose. Tested on Mac, Linux, and Windows with WSL, so week 1 is not lost to setup.
- A small default corpus. Under €15 of API for the whole course, with optional local embeddings.
- Invite-only community. Peers and accountability, during the cohort and after.
Bonuses for the founding cohort. The 100-pair reference golden set, the most expensive and most reused asset in the course, handed to you on day one. A poisoned-corpus security battery to test your defenses against instruction injection through retrieved content. And an OpenTelemetry tracing setup with per-request cost attribution, wired in.
What this would cost you otherwise
- An AI engineering master's or bootcamp: five figures, and retrieval gets two sessions. Here it is the entire course, and someone reads the code you write.
- Hiring a senior to design and review a retrieval system: $150+/hour. Ten weeks of weekly, line-by-line review runs deep into five figures.
- Figuring it out from blog posts and an AI assistant: free, and you end up with a pipeline that runs, that you cannot measure, and that nobody understands. That is exactly the failure this course exists to prevent.
Founding-cohort pricing is set below all of that, and the waitlist hears it first.
Proof: the method has a track record
Cohort 2 hasn't run yet, but the way it's taught has. Here is what Cohort 1 developers said about the same Test-Driven Coaching, on the same coaches.
"Agentic development has become a popular topic lately and the noise can overshadow its essence. Through the 6 weeks of the program we built a production-ready agent, and Bob and Juanjo guided us through understanding and applying the patterns used by seniors in the industry." — Daniele E.
"I learned stuff about pytest, I learned stuff about mocking, and I learned stuff about my own code. I just ended up thinking about things in a different way. It's different having done it than even reading about it." — Jeff Haemer, writing software since the early 1980s. He shipped an agent with three interfaces and ~250 tests at 100% coverage.
The coaching backbone: 150+ developers coached since 2020 · 500+ exercises across Pybites Platform and Rust Platform · 22+ years industrial operations engineering before AI. Same system, now on the retrieval layer.
Who this is for
Developers who already have an agent working and hit the wall where it retrieves the wrong thing, cites nothing, or degrades the moment the codebase grows.
You should be comfortable with modern Python, pytest, typing, and basic async, and you should have built at least one agent with tools. Cohort 1 is the natural prerequisite; equivalent experience counts. If you're missing the async piece, we can point you at a short leveling package before the start.
Time commitment: 6 to 8 hours per week on the 10-week track.
This is the harder cohort. If you want a gentler on-ramp to agents, start with Cohort 1.
Our guarantee
Do the work and push a PR every week. If by the end you have not shipped a coding agent that indexes a real repo, answers with provenance, and proposes patches verified by test execution, we keep coaching you, free, until you do. The only way this fails is if you don't write the code. And writing the code is the entire point.
Your coaches
Juan José Expósito González, Python & AI Mentor and PhD Engineer. Guides developers from Python basics to advanced AI implementations. Expert in Python, machine learning, blockchain, and algorithmic trading. Turns complex concepts into clean, testable, deployable architecture.
Bob Belderbos, developer coach and builder with 11 years at Sun/Oracle and 6+ years running Python coaching programs. Co-founded Pybites and built Pybites Platform (400+ Python exercises). Brings the architecture perspective: clean code, testable design, and the bridge between AI prototypes and production systems.
Frequently asked questions
When does it start? The founding cohort is being built now, with a small first intake. The waitlist gets the date and founding pricing before anyone else.
How long is it? 8 to 10 weeks depending on the variant we run, at 6 to 8 hours per week. The 10-week track builds the most from scratch; the 8-week track hands over the source adapters and compresses the same arc.
Do I need to have done Cohort 1? No, but you need the equivalent: modern Python, pytest, typing, basic async, and at least one agent with tools you've built yourself. This is not an introduction to agents.
What will API costs be? Under €15 for the whole course with the default corpus, and optional local embeddings if you'd rather run more of it on your own machine.
Is this RAG? It's the engineering underneath RAG, done properly: ingestion, chunking, hybrid retrieval, reranking, evaluation, freshness, and a propose-and-verify loop with a deterministic oracle. You'll leave knowing why most RAG demos fall apart in production, because you'll have measured it.
Why not just use a framework? Frameworks hide the loop and the index, which are exactly what you're here to understand. You build those by hand and use libraries for everything that isn't the lesson. That's the whole point of the measurement block.
Get first access
The founding cohort is small and being built now. Add your email to hear the start date and founding pricing before they're public, and to get the reference golden set the day it ships.
Join the waitlist for the founding cohort
This one is being built now, and the first cohort is small. Add your email to get first word when seats open, founding pricing, and the reference golden set the day it ships. No commitment; leave anytime.
No spam. Unsubscribe anytime.
Cohort 1 taught you to build the agent. This one teaches you to build what it can trust.